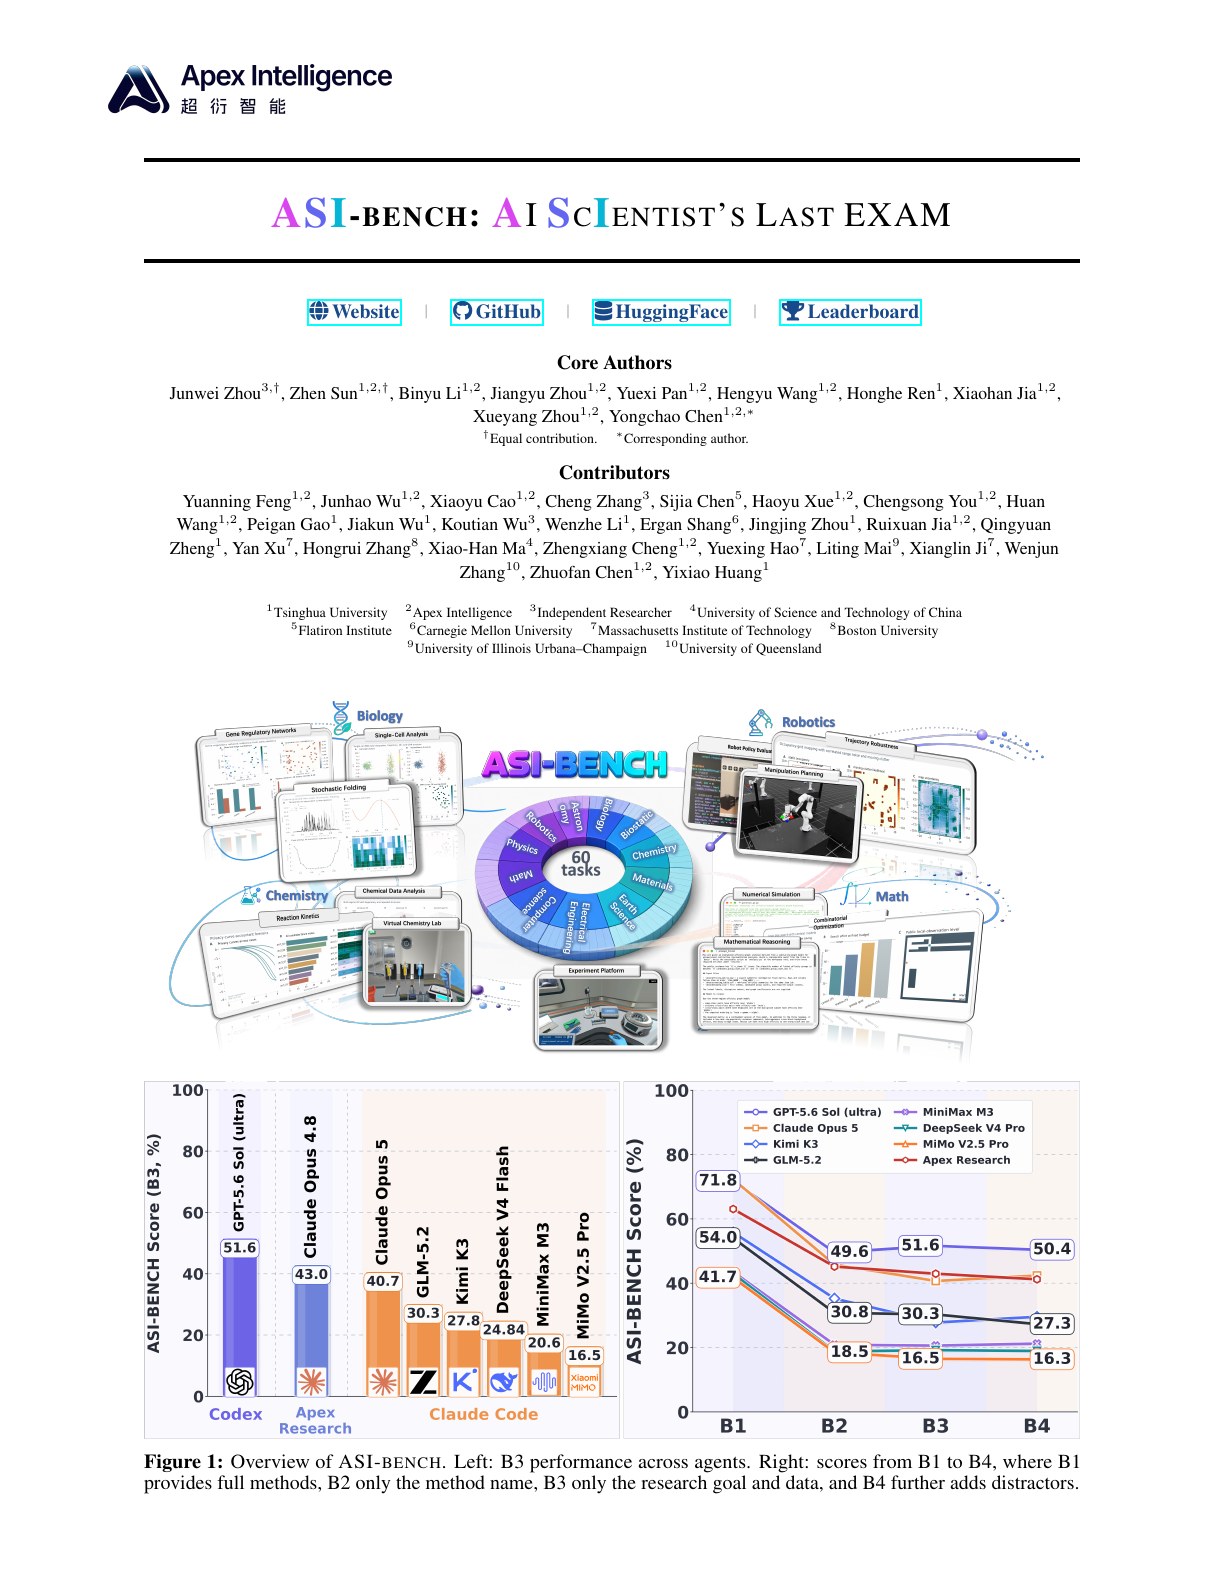
ASI-Bench is a benchmark from Apex Intelligence that tests how far AI agents can carry a complete scientific research project as human methodological guidance is removed.
Measuring research, not recall
Most benchmarks measure whether a model can recover known answers. ASI-Bench instead evaluates innovative exploration and autonomous scientific execution across complete research projects.
Built by more than 40 experts over 31,000+ human hours, the benchmark contains 60 project-level tasks across 11 scientific domains. Each task is reviewed, audited and executed in a sandbox with validated scorers.
Withdrawing methodological guidance
Within the same research project, the benchmark progressively removes human guidance. Systems are first given a full method, then only the method name, and finally must determine the method themselves. The performance drop across these stages exposes current dependence on human research judgment.
Across 18 state-of-the-art agent-model configurations, the average score falls from 50.91 with full methodological guidance to 29.10 with only the method specified, and to 26.62 when agents must choose the method themselves.
Scientific autonomy is revealed not by a correct final answer alone, but by the ability to choose methods, conduct work and produce verifiable outcomes.
Open participation
The task catalog, evaluation framework and public leaderboard invite researchers and builders to contribute new tasks and test the limits of current systems.
Abstract
Artificial superintelligence (ASI) requires AI to move beyond mastering existing knowledge toward exploring the unknown, creating new knowledge, and turning new ideas into verifiable results. However, the capabilities of today’s AI systems are still largely built on learning, compressing, and applying existing human knowledge. Accordingly, existing benchmarks primarily test whether AI can produce correct answers based on learned knowledge, or whether it can complete tasks under extensive human guidance. We therefore introduce ASI-Bench, the first benchmark to jointly evaluate AI systems’ capabilities of innovative exploration and autonomous scientific execution across general research domains, and the first to progressively withdraw human methodological guidance within the same research project to test how far AI can proceed on its own. Built by over 40 experts with the cost of 31,000+ human hours, ASI-Bench contains 60 project-level research tasks across 11 scientific domains and progressively reduces methodological guidance to test whether AI can independently select methods, conduct research, and produce verifiable results. All tasks undergo expert review, AI-assisted auditing, sandbox execution, and scorer validation. Across 18 state-of-the-art agent-model configurations, the average score drops from 50.91 with full methodological guidance to 29.10 with only the method specified and 26.62 when agents must determine the method themselves. This sharp decline shows that current systems remain heavily dependent on human guidance and are still far from autonomously conducting end-to-end, project-level scientific research. ASI-Bench is open to the world. We invite researchers and builders everywhere to contribute new tasks, challenge the limits of today’s AI, and help accelerate humanity’s collective path toward artificial superintelligence at asibench.apexin.ai/submit.
Core authors: Junwei Zhou5,†, Zhen Sun1,†, Binyu Li1, Jiangyu Zhou1, Yuexi Pan1, Hengyu Wang1, Honghe Ren1, Xiaohan Jia1, Xueyang Zhou1, Xiaoyu Cao1, Yongchao Chen1,*
Contributors: Yuanning Feng1, Junhao Wu1, Cheng Zhang13, Sijia Chen10, Haoyu Xue1, Chengsong You1, Huan Wang1, Koutian Wu13, Peigan Gao9, Jiakun Wu1, Wenzhe Li1, Ergan Shang4, Qingyuan Zheng1, Jingjing Zhou1, Ruixuan Jia1, Yan Xu2, Hongrui Zhang7, Xiao-Han Ma9, Zhengxiang Cheng1, Yuexing Hao2, Liting Mai6, Xianglin Ji2, Wenjun Zhang8, Zhuofan Chen1, Yixiao Huang1, Chi Wang12, Wenyue Hua11, Yilun Hao2, Yuantao Zhai1, Ziyan Zhao1, Jingyan Xie3
Affiliations: 1Tsinghua University · 2Massachusetts Institute of Technology · 3Harvard University · 4Carnegie Mellon University · 5University of Michigan · 6University of Illinois Urbana-Champaign · 7Boston University · 8University of Queensland · 9University of Science and Technology of China · 10Flatiron Institute · 11Microsoft Research · 12AG2 AI · 13Independent Researcher
†Equal contribution. *Corresponding author.